Our website uses cookies to enhance your browsing experience.

A language invented so that programmers would no longer be needed kickstarted a profession that is still around today and pays quite well. Another language was called "structured English", and people thought any accountant would be able to use it. It also spawned a new specialty with its own salary band. The attempt to deliver "programming without programmers by the year 2000" proved unsuccessful, too.
You might've recognized COBOL, which is still used daily and, by various estimates, sits behind 80% of ordinary (in-store) banking transactions, while its codebase runs to a couple of hundred billion lines and feeds tens, if not hundreds, of thousands of developers. Although, if you dig into those pretty numbers, almost all of them trace back to a single survey from the late nineties that was then endlessly re-extrapolated onto the whole world, so it's more fair to treat them as estimates rather than precise data.
SQL spawned the peculiar caste of DBAs (Database Administrators) and Data Engineers, and today a person who writes "simple queries" can easily earn a mid-level salary. Meanwhile, the language itself has become so complex that modern dialects (PostgreSQL, Oracle) are full-fledged programming languages with procedural logic, where you can write absolutely anything, from a fractal generator to a game engine.
The 4GL family was a "golden cage" that worked beautifully for building typical "input-output" forms. However, as soon as non-standard business logic or an integration with an external service was required, the tool hit its limits. Developers then had to bolt on "crutches" in low-level languages, turning development into a hellish cocktail of visual design and dirty hacks. And instead of programmers disappearing, 4GL created "enterprise system architects" (SAP ABAP, for example) who became insanely expensive experts. It didn't eliminate programming either but moved it out of the zone of "general-purpose languages" and into the zone of "expensive and temperamental tools" that lock a company to a particular vendor.
Every ten to fifteen years the industry solemnly announces that the need for manual coding will soon disappear, offering a new way to "explain tasks to machines in plain human language.". And every few years, we can see the number of programmers going up rather than down, but they just get a new name. I would venture that right now we're living through another turn of this cycle, and the new name for such people will be "vibe coders". I also think AI is destined to meet the same fate as the previous attempts.
The idea of "talking to a machine in human language" is older than the very notion of a computer. Science fiction from the first half of the twentieth century is full of it: from Fritz Lang's "Metropolis", which will turn a hundred years old any minute now, with its mechanical double of a human being, to stories where the machine is given orders by voice and obediently carries them out. But as soon as real computing machines appeared in the forties, it became clear that the problem was not the machine.
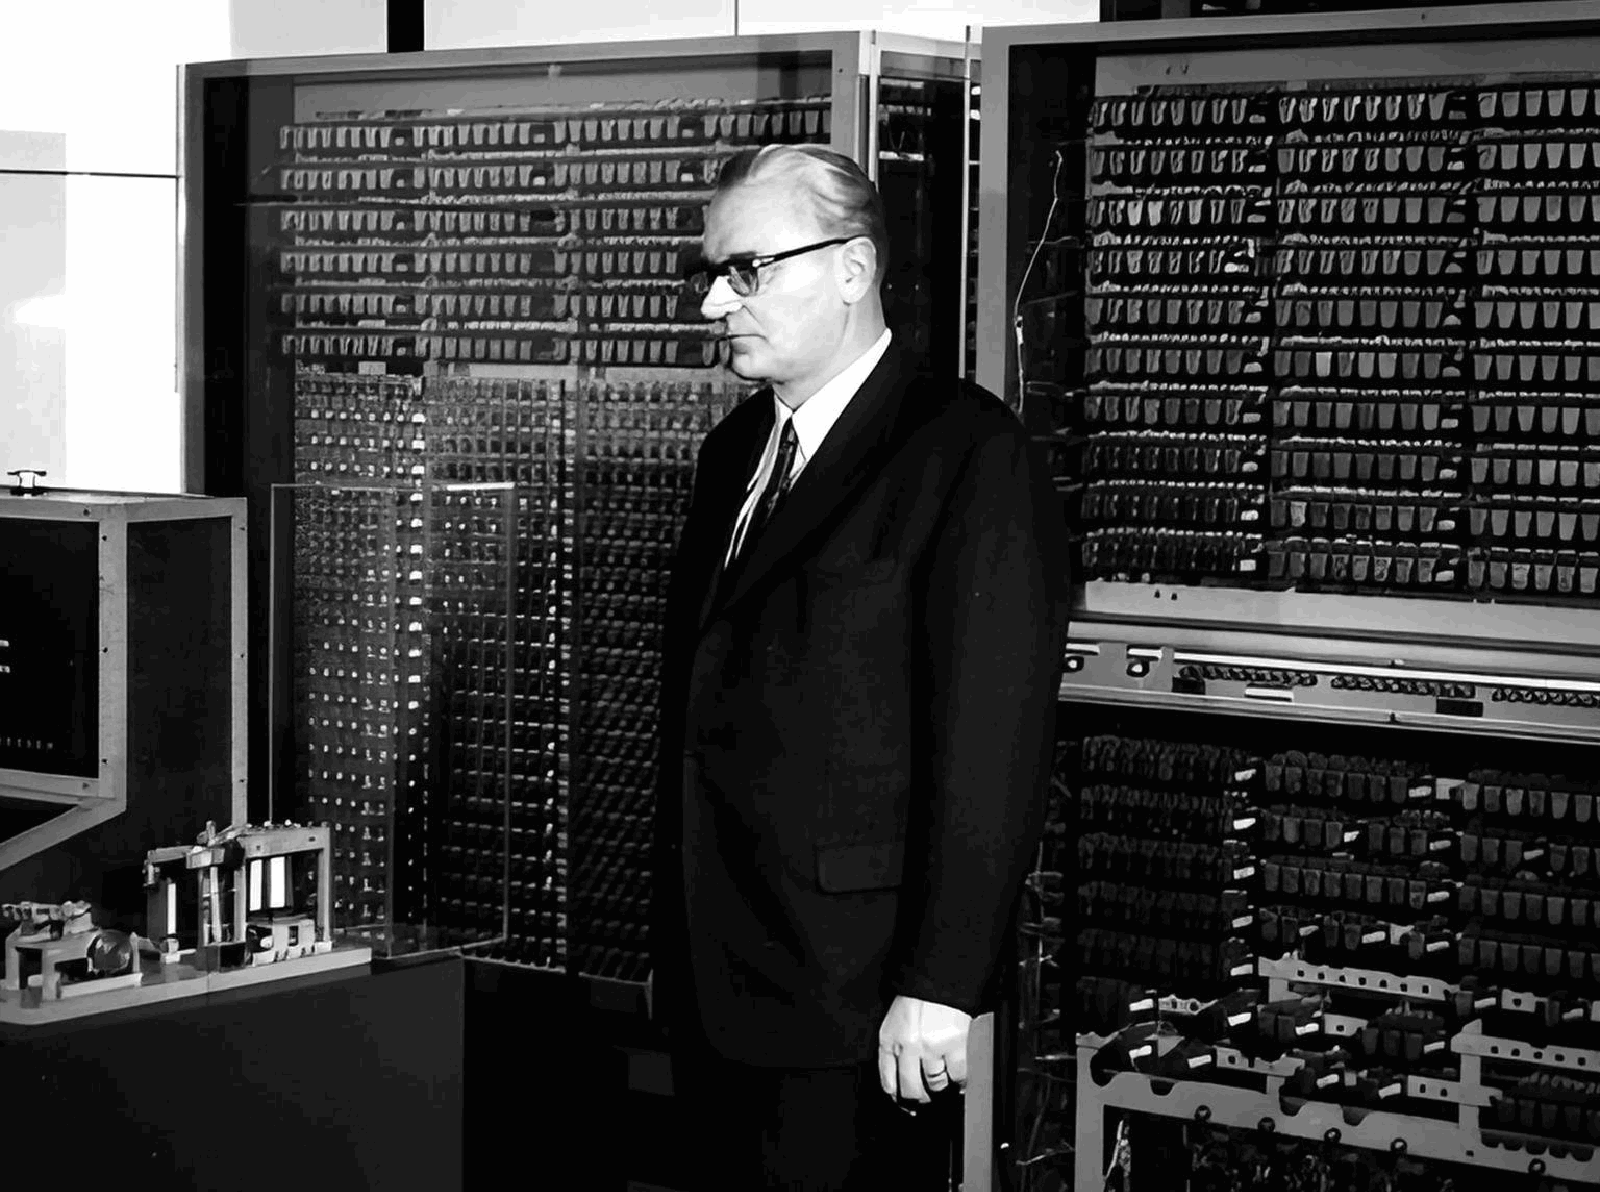
Konrad Zuse, who built the Z3 in 1941 and developed one of the first high-level languages (Plankalkül), framed the problem like this: "The danger of computers becoming like humans is not as great as the danger of humans becoming like computers." I know many developers who really treat programming languages as poor substitutes for English. I won't argue with them... They aren't "bad versions of English," but rather tools with fundamentally different properties, no worse than natural language and no better; they're simply different.
What does the phrase "calculate the quarterly bonuses for the employees" mean to an accountant? Early in my career, I worked at a small company that contributed to the entropy of the world by developing something like a payroll engine, so I got a little taste of that stuff. For a living human being that single phrase would be enough to ask a dozen of questions: who exactly gets a bonus? What formula to use? What about employees who joined midway through the quarter? What to do with those who quit? Should the figures be rounded, and if so, in which direction? What currency to use? What to do if no data is available for an employee? Natural language works precisely because the listener fills in those gaps with context, common sense and general knowledge, of which they have plenty, because they work in that field.
A program and code... can't do that. Each of those decisions has to be pinned down somewhere, propped up, spelled out as a procedure. Otherwise, the result will be non-deterministic, and non-deterministic accounting isn't accounting; it's grounds for a conversation with the IRS. Often, even experienced accountants can't take everything into account at once, so a short phrase in natural language unfolds into something like this:
"calculate the quarterly bonuses"
    ▼
- which quarter exactly (calendar? fiscal? counted from the hire date?)
- who is included (staff? part-timers? those who quit mid-quarter?)
- the accrual base (base salary? salary + overtime? average for the period?)
- the formula (a percentage? a fixed sum? a progressive scale?)
- proration for a partial quarter (by days? by months? none at all?)
- rounding (half-up? down? to the dollar? to the cent?)
- currency and exchange rate (as of which date do we take the rate?)
- missing data (skip it? treat it as zero? crash with an error?)
Eight questions out of one, and I was being lazy at that. Every question spawns even more questions, and once it stops doing so, you can describe it in the terms of programming languages.
A programming language exists for this tedious precision, not in spite of it. It provides a syntax where ambiguity is physically inexpressible, and semantics in which the same program always means the same thing. A programmer who "translates" the requests of a manager and an accountant into code isn't translating a spec into code. Rather, they take on those eight or more questions and assume responsibility for the answers.
...doesn't work. There are reasons why the idea of "natural language instead of code" hits its limits, and they are about us... humans, not about the tools, compilers, standard libraries, or the limitations of existing programming languages. And the main one is the inherent ambiguity of natural languages.
What would you do if you were asked to "delete all files older than 30 days in this folder"? Most likely you would just select the files by modification date and delete them... It looks like a simple action, but you have just used your experience to answer 90% of the sub-questions. And there are quite a few of those sub-questions once you start articulating the main one:
— Older by creation date or by modification date?
— Do we include subfolders and the files in them?
— Do we delete hidden files?
— What about symlinks? Do we delete the link or the file itself?
... and so on.
To remove the ambiguity you either have to ask a series of clarifying questions, effectively writing the program's code in words, or make the decisions on behalf the person who asked, possibly doing other than what they wanted. Programming languages resolve those sub-questions with brute logic, because every construct has exactly one meaning, and mtime never suddenly turns into ctime.
However, even having answered every question and every sub-question precisely, we still run into Rice's theorem, a rather boring mathematical treatise from 1953 with a joyless real-world implication for us humans. It goes like this: "No non-trivial semantic property of a program can be checked algorithmically in the general case". That is, you can't automatically guarantee that the generated code does exactly what was asked, which means somebody has to check what came out. To check the code, you have to read it; and to read the code, you need a formal language. We've come full circle.
Another property indirectly comes to light, no longer about Rice but about natural language itself. The more complex a composition we want to build, the worse it maps onto words. In plain terms, it sounds like this: a small function can be described in words, and it'll even come out decent and clear, but a million-line system can't be described in words. The problem isn't a lack of words; natural language simply doesn't compose. Meanings can overlap and flow from one sentence to the next or depend on neighboring sentences, capturing paragraphs and sometimes even larger stretches of the text.
What follows is a difficult block, I've hidden it under a spoiler. If linguistics isn't your thing, you can scroll to the next section, where the idea is repeated through things and comparisons a developer will understand.
However, if you're curious where this "irreducibility to words" comes from at all, linguists described it long ago and in detail, long before any AI. They tried to formally define and compute the meanings of an ordinary human phrase, and discovered that the meaning of a sentence can't be computed by looking at the sentence alone. No text in natural language can be carried over as is into other forms of representation without losing context or the meaning of individual parts. The process of carrying it over requires splitting the shared context into parts, which means assessing the essential complexity of the task.
A programmer is in this state before writing any code; it's called... drum roll... analysis paralysis (sometimes also called Brooks' stupor, as the process of overcoming that very essential complexity). The idea of "just tell the machine in words" stumbles over this state, and so does the top-down "here is a spec in words, go write a program in...", so it's worth taking a look at what has been dug up over forty years.
But natural language has another affliction, and this one isn't about Rice. The sentences themselves may be built illogically, tripled up, smudged and back-to-front invented, twisted and tangled, cut inside out and woven every which way, so that there's more than one path in that garden of words, and the paths there fork right in the middle of the phrase, and you realize it only once you have read to the end, or even reread from the beginning. Not that I was ever a great linguist, but at the end of 2010s I had to extend a profanity filter in one of our apps, and in the great and mighty Russian tongue one could tell someone off in a great many ways, so I had to touch on this topic a little as well. But let's get back to our muttons... that is, our words.
As long as we speak in small phrases like "delete the file", everything is fine: the whole phrase fits into your head and doesn't drag a tail of context behind it. But when we try to describe something more complicated in words, they start to "get in each other's way" or "depend on each other" across sentences, whereas a variable in a normal programming language should depend only on the precise context where it's used.
The classic phrase "every farmer who owns a donkey beats it" is clear to any English speaker and usually reads without a hitch. Now try to break it into parts and preserve the meaning of each part separately, the way a compiler does with an expression.
"Who owns a donkey" now merely asserts the existence of a donkey belonging to some farmer, while "beats it", taken apart from everything else, gives no clue at all as to who is being beaten, because "it" shows up after "donkey" has already flickered by and formally gone out of scope.
A human doesn't notice this, because they hold the whole chunk in their head and can reconstruct that connection on the fly. However, a function that computes the meaning of a sentence piece by piece from left to right, the way any normal parser does, will either break or be so complex that it's not worth discussing its practical application.
For a programmer, this would be a variable declared inside one function and yet visible in the next one too, without being passed explicitly and without global, because somewhere the usage context got snagged. No language allows that, and scopes were invented precisely so that such a thing would be impossible by design. Natural languages, on the other hand, live on this very concept: its "donkey" leaks across the sentence boundary, and that counts as normal behavior.
The context leak was described by linguists long before any AI: in the early eighties Hans Kamp did so in his work on dynamic semantics and, almost simultaneously, Irene Heim in her dissertation on file change semantics. They both came to the same conclusion independently: the meaning of a sentence can't be computed without dragging along what was said earlier.
That is how discourse representation theory, DRT, was born. It's single practical conclusion for us programmers sounds boring and inapplicable, because in its "natural habitat" it works outside DRT. It's impossible to formally guarantee that a piece of text can be understood in isolation from the neighboring pieces. So, it's impossible to expect a language used to explain a task to a machine to behave like code while remaining a natural language.
A programmer's natural habitat is Code, and Code is free of this disease, and the calculateAge(1985, 2026) call means the same thing whether you stick it into a game loop or into a report for the IRS. It drags no invisible tail of previous lines that change its meaning.
A programmer's job is to assemble a Big System out of independent pieces, which is possible only if the pieces don't change their meaning depending on where you put them. Natural language is fundamentally incapable of that: the state of a small sentence drifts with the size of the context you shove it into. Hardly anyone would be pleased if the result of sum(a + b) suddenly started depending on the length of the calling function.
I hope I haven't worn you out too much with this discourse.
To start with, you can look at the Stanford Encyclopedia of Philosophy articles: "Discourse Representation Theory" and "Dynamic Semantics". They're free, proofread by experts, and written in accessible language, unlike Kamp's original.
The next level is the primary sources, the paper "A Theory of Truth and Semantic Representation" and Irene Heim's dissertation "The Semantics of Definite and Indefinite Noun Phrases". It's worth at least leafing through them to see that they aren't esoteric but rather an attempt to build that very "function over context" in the pre-AI era.
All this literature really is hard, and it looks like watery water in a bucket of water to a non-specialist, but note what it took to formally describe just one level of the Discourse Representation Structure (DRS) of natural-language semantics, and even that doesn't close out the theory of language as a whole.
Modern large language models aren't built on DRT, they're statistical transformers rather than Kamp's theory. So, this isn't the foundation of AI but the story of why functions over context run into such complexity and terabytes of RAM just so you can ask a model for Lenin's birthday. Also, to understand why the idea of making natural language a precise specification language looks naive. That's what vibe coders are selling right now as the dream of "English instead of code".
Throughout history, there have been several attempts to create a programming language that resembles English to eliminate the need for programmers. Funnily enough, every one of them produced the same side effect: the old programmers stayed, but new professions were born, giving work to a new generation of programmers.
COBOL (1959) was created with the goal of letting managers and business analysts read and write programs. That is why the syntax was deliberately designed to look like English sentences: ADD SALARY TO TOTAL GIVING NEW-TOTAL reads like an almost normal sentence. The result was the COBOL programmer profession, which is still alive today and runs many banking and government systems, as I said at the beginning of the article. However, managers never started using in it. They continued to write reports by hand or in Word and create tables and diagrams. They also started delegating assignments to COBOL developers.
Then, the era of SQL came (1974). It was originally called SEQUEL—Structured English Query Language —because it was designed to enable not tech-savvy people ask a "program" questions in almost-English. Later, it was renamed to SQL for advertising and money reasons, but the intent of "English for queries" stayed sewn right into the name. Today, an SQL developer is a separate profession, and the "non-technical manager person" who runs into LEFT JOIN with three subqueries and a window function usually calls a technical one who understands this complex construction.
Then, there were 4GL and CASE (Computer-Aided Software Engineering, the eighties), which are considered fourth-generation "natural programming languages". Once again, they promised "programming without programmers". By the end of the 1980s, advertising was so powerful that many people were genuinely afraid of the "empty office" effect. In this scenario, most applications would be created without writing code, which would cause developers to switch to other professions. But again, by the year two thousand, the industry had not only failed to get rid of programmers, it had also acquired a plethora of new, highly paid specialists in SAP, Oracle, and proprietary frameworks.
As it turned out, the "naturalness" of 4GL systems was just another illusion, like COBOL and SQL before it. It merely hid a monstrous configuration complexity and unpredictable system behavior behind a facade of visual blocks. The more the CASE tools tried to automate writing code, the more time programmers spent fighting the limitations of those very tools, turning from creators of logic into "architects of system integrations". Eventually, instead of developers disappearing, we got a shortage of them, while "programming without programmers" simply moved to a different plane. Instead of writing code in C++ or Pascal, you now have to learn a particular vendor's "secret knowledge," turning the visual builder into yet another expensive programming tool.
And it's really expensive, because the salary of a SAP developer easily exceeds $100k, not to mention the cost of training and annual exams. On top of that, there's training at $Xk and mandatory yearly recertification. Without the latter, the certificate simply expires, and all of it is tied to the vendor's own paid subscription.
Then came the turn of UML and Model-Driven Architecture (the nineties and the noughties) with the beautiful idea of drawing diagrams that would generate code. In reality, UML survived as a documentation and diagram tool for developers who then write the code manually anyway, and sometimes draw the diagrams from code that has already been written, which sort of hints at something. Then funding for UML dried up significantly, and in the early 2010s, the people who had been promoting Model-Driven Architecture flocked en masse to no-code and low-code startups and companies of all types and sizes—which also seems to hint at something.
Bubble, Webflow, OutSystems, and Mendix began marketing to anyone who wanted it, claiming that "now any business can build its own app." In reality, it came down to standard tasks, forms, CRUD interfaces, and automations, with their own coaches, schools, tools, and support. However, as soon as non-standard logic, integration, or performance is needed, you have to build crutches out of blocks within the platform or hire a developer who knows the platform well enough to write "normal" code in C++, Java, Swift, or whatever language you prefer. So, surprise, surprise... yet another profession emerged. It turned out that the industry selling the dream of "you don't need a developer anymore" was also selling certificates saying "I am a developer for this thing" on the side for a modest profit. And then came the LLMs' turn...
You're here, and this time things are really different from the previous ones: for the first time, the tool started working with arbitrary natural language rather than with a limited DSL made of blocks, diagrams, and special words. That is a very big leap comparable to COBOL/SQL/UML and the rest, and I say that without any irony. However, the fundamental limitations of ambiguity, verifiability, and reproducibility remain because they're inherent to the nature of the task, not the tool. Somebody still has to state the task precisely and in small portions, read the generated code, and answer for what that code is going to do in production at three in the morning.
If you look back at this list, you'll see that every wave really did kill off some layer of manual work; but every wave also created a new layer of work on top of itself.
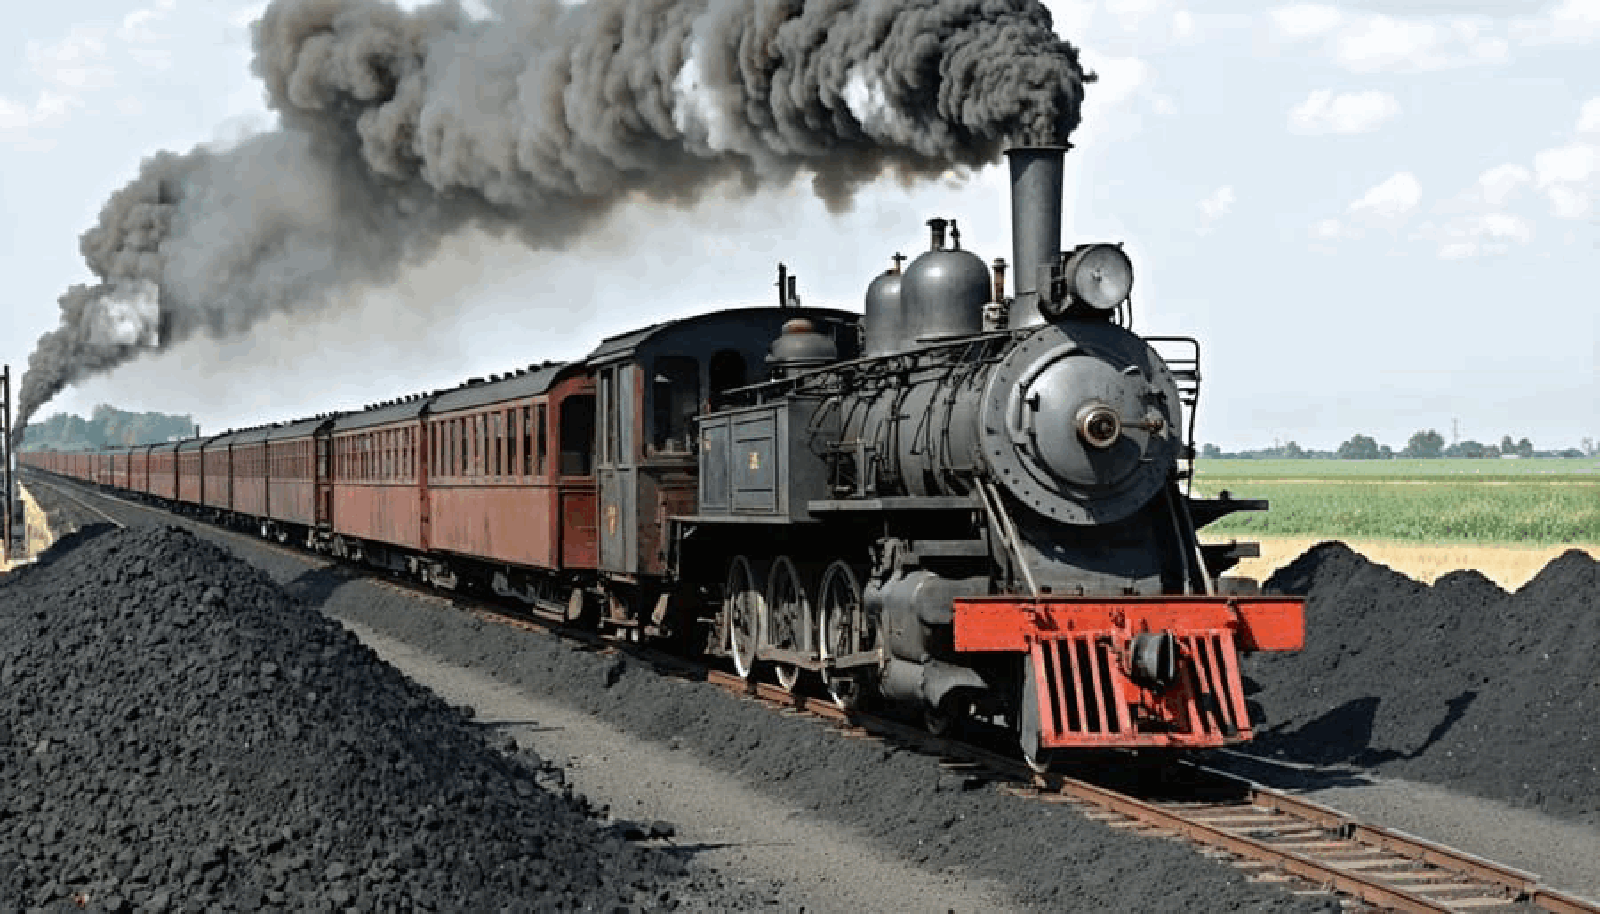
In 1865, William Stanley Jevons noticed that as steam engines became more efficient and required less coal to produce a unit of work, more coal was consumed overall. The now cheaper unit of work opened up many new applications, increasing the total volume of work needed.
Every time a tool makes writing code cheaper, demand for software grows faster than its production cost falls. That is how the number of programmers grew from a few thousand in the early fifties to hundreds of thousands in the nineties, from millions in the two thousands to tens of millions today, despite the fact that a modern developer has a framework, an IDE, a package manager, and search engines...
Sometimes, they accidentally ship in a single day as much as their colleague from the last century would write over days and months because the productivity of an average programmer has grown by orders of magnitude. Their workload has grown as well because cheap code has made worthwhile projects that businesses wouldn't have dared to start before. So, if your intuition tells you, "The tool does the work for me, so there 'll be less work", Jevons has some bad news for you, and it's a hundred and sixty years old.
However, none of the above means that nothing changes—it does, and quite a lot, just not in the direction we can see. The bottom of the market is going away: boilerplate code, simple CRUD systems, markup, and boilerplate generation—all the work where the solution is already there and just needs to be typed out. This is where AI truly shines.
But the top is growing: designing systems, understanding the domain, debugging, performance optimization (one of the areas where even the almighty Claude floats like an axe and sh*tclaudes away, so you barely keep up rejecting the commits), security, and embedding components into systems that must work predictably. Somebody has to check what the generator's generator generated with a generator, right? And that somebody has to understand the System—no, not even the Code...—more deeply than the one who generated it, because the one who generated it runs into Rice's theorem and Kamp's work.
You could say that the limits of what machines can do are shifting quickly, but the limits of what businesses need are shifting even faster. Programmers don't disappear in this environment, but the composition of their work changes: there's less manual typing now, more thinking, and you're still responsible for everything.
What keeps programming languages afloat isn't syntax, developers' habits, or the industry's resistance to change—although there's plenty of resistance, too. Programming languages solve tasks that natural languages (regardless of the tool used) are fundamentally unsuited for neither as diagrams, nor as md files, plans, or dialogues with Claude. A programming language unambiguously describes the behavior of systems that must work predictably.
As long as there are systems for which "approximately right" means losing profit, time, or taking damage—and that includes most banks, all of medicine, all of aviation, and possibly most ordinary businesses—a formal way to describe exactly what they must do will be needed. That formal way is the programming language, however it may look by 2050, whether it's text, voice, or a thought channeled straight out of your head.
A machine that accepts "I want a million dollars" and magically delivers is still a science-fiction plot from the beginning of the last century rather than engineering reality, because somebody will have to tell the machine where that money comes from, in which currency, which account to transfer it to, and what to do if, instead of money, some lads in short jackets turn up. That somebody is the programmer, except for the case with the lads, regardless of whether they manually type transfer(amount, account), chat with a bot, or narrate it to an assistant by voice.
I'm leading you to a conclusion about what has always been the foundation of the programming profession. Vibe coding didn't eliminate the need to state the task precisely; it merely shifted the point at which you pay the price for imprecise wording. So, once again, the problem hasn't been solved, and it can't be solved at all. However, as usual, we can push it up to the level of a technical person, only now they will be called something else: Senior Opus Engineer, for example. In about ten years, someone on Habr will write an article about the origin of this new profession and its salary band. Agreed?
The PVS-Studio team loves to publish valuable content for developers. Subscribe to our newsletter to follow the articles from the PVS-Studio website.
Here are some articles:


0
0
0

0